String matching is an important problem in several fields of computer science such as bioinformatics, data compression, and search engines. I find it amazing that search engines can find exact string matches in massive datasets in essentially constant time. Having the ability to do this would be very useful for when I create data compression algorithms!
Last night I downloaded the entire English Wikipedia, which turned out to be a 31.6GiB XML file. I spent the day trying to solve the following problem: how to quickly find strings in this massive file. The hardest constraint in solving this problem is the fact that my computer only has about 3GiB of memory. Somehow I needed to preprocess the 32GiB file into 3GiB of memory and then *only* use the 3GiB of memory to find the location of arbitrary strings in constant time. Solving this problem exactly is impossible, so the goal of the project is to maximize the likelihood that the match I find is correct.
I tried doing some research online and was surprised that I couldn't find many helpful resources. This is surprising since this seems like such an important problem. I will describe the algorithm I ended up implementing:
I stored all of the data in two arrays. The first array stored positions in the XML file, type = long, dimension = 20000000x4. The second array stored counts, type = int, dimension = 20000000. The first step was to go through the 32GiB XML file and extract every substring of length 25. These substrings are keys that I used to store in the arrays. I computed a hash for each key to use as an array index. The second array was used to keep track of the number of keys put in each array position, so it is simply incremented for each key. The first array is used to store the position of up to four substrings. I stored the position of a particular key with a probability that depends on the number of colliding keys (the count stored in the second array). More collisions = less likely to store the position.
OK, so the algorithm so far preprocessed the 32GiB file into about 700MiB of memory. Now comes the fun part of using the data to do string matching. Given a string to search for, I first extract every substring of length 25. I hash each substring and collect the locations that are stored at those positions in the first array. Only a small fraction of these matches are likely to actually correspond to the string we are searching for. The essential piece of information that helps find the true match is the fact that the offset of the substrings in our search query should match the corresponding offset of matches returned from the data. It is possible to find the best match in O(n) time (where n is the length of the search query).
To sum it up: I preprocess the data in O(m) time (where m is the length of the data). I can then do string matching in O(n) time (where n is the length of the search query).
So how well did this work on the dataset? It took something like 1 hour to preprocess the XML file (basically the amount of time required to read the entire file from disk). The search queries run remarkably fast - no noticeable delay even for queries that are hundreds of thousands of characters long. The longer the search query, the more likely the algorithm is to return the correct match location. For queries of length 50, it seems to match correctly about half of the time. For queries over length 100, it is almost always correct. Success!
Interesting fact: my algorithm is somewhat similar to how Shazam works. Shazam is a program that can look up the name of a song given a short recorded sample of it. The longer the recording, the more likely the correct match is returned.
Tuesday, September 06, 2011

Saturday, September 03, 2011
Gold Promotion
I recently got promoted to gold league:
 Here is the army graph for a match I am proud of:
 The enemy completely destroyed my army and my main base. I think they started taking it easy after my main base went down - I made a huge comeback and eventually won the game :)


Saturday, July 09, 2011
RoboCup
I have been in Istanbul, Turkey for the last week at the RoboCup robotics competition. We are competing in the small size league. Today we finished our last official match. Although the final rankings have not been released yet, we think our team placed 9th (out of 20). We ranked well in the technical challenges: 3rd place in the navigation challenge and 3rd place in the mixed team challenge.
Master's Thesis
I finished my master's thesis! The final copy is posted here. Now that my thesis is done I can start work at Google. My start date is July 18.
Friday, July 08, 2011
Crater Detection
The contest has finished and my final ranking was 6th place. One rank away from a prize! The approach I used was using template matching and the normalized cross-correlation distance metric.
Tuesday, June 28, 2011
Crater Detection
NASA is hosting a TopCoder marathon match to detect craters in satellite images. The contest lasts about two weeks and there are $10,000 in prizes (for the top five competitors). The task is to return a list of crater positions and sizes for a set of satellite images. There is a little over a day remaining in the contest and I am currently ranked third. If I end up doing well in the final rankings I will make a blog post about the technique I used. Here are a few example images in the training set:


Tuesday, June 21, 2011
Bitcoin
I recently started bitcoin mining using my GeForce GTX 260. Some of my friends have invested thousands of dollars into bitcoin mining hardware and have already earned back more than they invested. Bitcoin mining seems to be the latest fad among CS students. Unfortunately my mining rate is pitifully slow, so I gave up after a few days. I earned 0.5 bitcoins in slush's pool. I held an auction for my 0.5 BTC on IRC and got payed $5 CAD for it.
Saturday, May 28, 2011

Saturday, May 21, 2011
Website Exploit
Within a few hours of launching my Rock Paper Scissors website somebody found an exploit. The exploit caused all users to be forwarded to another site. I have now fixed and prevented this particular exploit. An exciting website debut!
Rock Paper Scissors

Over the last two days I implemented a new website: Rock Paper Scissors Programming Contest. It is amazing how fast a relatively complex website can be created using Google App Engine. It has probably been one of the funnest programming projects I have worked on!
I think the website could potentially lead to some innovative research. All of the submissions are open-source, so if the website becomes popular I will be very interested to see how the best AIs work. It should be possible to directly convert any RPS algorithm into a compression algorithm - there should even be a correlation between RPS performance and compression performance.
I encourage anyone who is reading this to try submitting an entry. Programming a RPS AI should be pretty fun. Python is also very easy to learn, so even people who have no programming experience should give it a try!
Monday, May 16, 2011
Promote Me!
In Starcraft 2 I am currently rank 2 of bronze league. However, from what I understand the rank within a league is not very meaningful - the important number is called MMR. MMR determines league promotions and demotions. Blizzard keeps the MMR statistic hidden from players. I actually think this is a poor design decision since the benefits of releasing MMR seem to far outweigh the benefits of hiding it.
I have been practicing and optimizing a single strategy which seems to be doing pretty well. I won 17 of my last 18 matches - against bronze, silver, and gold players. The fact that I am winning against gold players should indicate that I need to be promoted from the bronze league. However, Blizzard's algorithm seems to think otherwise and wants me to stay in bronze :(
I have been practicing and optimizing a single strategy which seems to be doing pretty well. I won 17 of my last 18 matches - against bronze, silver, and gold players. The fact that I am winning against gold players should indicate that I need to be promoted from the bronze league. However, Blizzard's algorithm seems to think otherwise and wants me to stay in bronze :(
Tuesday, May 10, 2011
Starcraft II
Last week I bought Starcraft II. The game has already been out for a year, so I am late to the party. I also never played the original Starcraft (which has been out for 13 years), so you can imagine that I am terrible at the game.
I have spent a lot of time over the last week studying and practicing. I found the beginner guide at /r/starcraft to be quite helpful. I have also been watching Husky and day[9] videos. This is my favorite match so far. I find watching Starcraft matches quite entertaining, so I anticipate that I will continue watching matches even if I stop playing the game.
I play as Terran (username: omninox). I have started focusing on a single build order that seems to be doing quite well. I have been slowly rising in the bronze league - hopefully I will be promoted to silver soon. Most of my friends are way better than me, so I have been doing 1v1s with strangers. One player I know (a friend of a friend) is ranked at the top of the master league!
I made it to the last level of the campaign on hard difficulty. After a number of retries on the last level, I gave up and beat it on normal. I have also started playing two custom Starcraft games: starjeweled and desert strike. I have been using starjeweled as a way to relax between 1v1 rounds - I find 1v1 to be quite mentally exhausting. Desert strike is a great way to practice unit counter strategies. If you play Starcraft, send me a friend request and maybe we can play sometime.
I have spent a lot of time over the last week studying and practicing. I found the beginner guide at /r/starcraft to be quite helpful. I have also been watching Husky and day[9] videos. This is my favorite match so far. I find watching Starcraft matches quite entertaining, so I anticipate that I will continue watching matches even if I stop playing the game.
I play as Terran (username: omninox). I have started focusing on a single build order that seems to be doing quite well. I have been slowly rising in the bronze league - hopefully I will be promoted to silver soon. Most of my friends are way better than me, so I have been doing 1v1s with strangers. One player I know (a friend of a friend) is ranked at the top of the master league!
I made it to the last level of the campaign on hard difficulty. After a number of retries on the last level, I gave up and beat it on normal. I have also started playing two custom Starcraft games: starjeweled and desert strike. I have been using starjeweled as a way to relax between 1v1 rounds - I find 1v1 to be quite mentally exhausting. Desert strike is a great way to practice unit counter strategies. If you play Starcraft, send me a friend request and maybe we can play sometime.
Thursday, April 28, 2011
Image Compression Results
Here are some more results comparing JPEG at the maximum compression level to my image compression algorithm:
Original image:

JPEG (15.7KiB):

My algorithm (3.2KiB):

Original image:
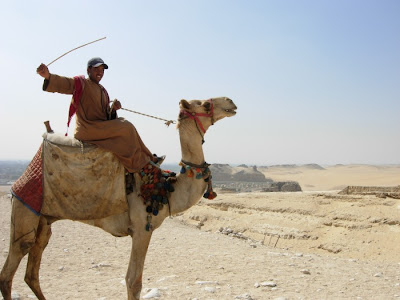
JPEG (6.3KiB):
My algorithm (2.0KiB):

Original image:

JPEG (6.2KiB):

My algorithm (3.9KiB):
Original image:
JPEG (11.2KiB):
My algorithm (2.8KiB):
Original image:

JPEG (7.1KiB):
My algorithm (3.0KiB):

Original image:
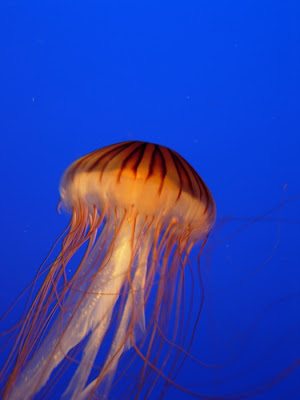
JPEG (5.9KiB):

My algorithm (1.5KiB):
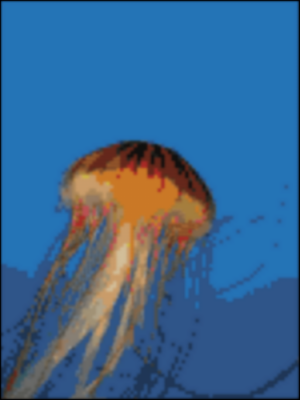
Original image:
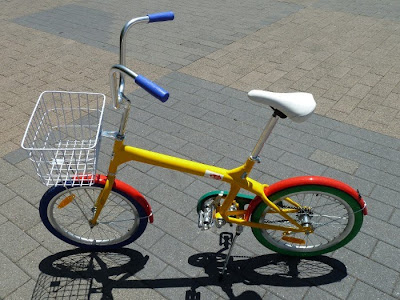
JPEG (16.4KiB):

My algorithm (4.0KiB):

All of the above images are around 1MiB when uncompressed. In every case my algorithm resulted in a smaller file size and a (arguably) better looking image.
Original image:

JPEG (15.7KiB):

My algorithm (3.2KiB):

Original image:

JPEG (6.3KiB):

My algorithm (2.0KiB):

Original image:

JPEG (6.2KiB):

My algorithm (3.9KiB):

Original image:

JPEG (11.2KiB):

My algorithm (2.8KiB):

Original image:

JPEG (7.1KiB):

My algorithm (3.0KiB):

Original image:

JPEG (5.9KiB):

My algorithm (1.5KiB):

Original image:

JPEG (16.4KiB):

My algorithm (4.0KiB):

All of the above images are around 1MiB when uncompressed. In every case my algorithm resulted in a smaller file size and a (arguably) better looking image.
Wednesday, April 27, 2011
Lossy Image Compression
Last night I wrote a lossy image compression algorithm. It is based on an idea from this paper. First I trained a set of 256 6x6 color filters on the CIFAR-10 image dataset. To train the filters, I used the k-means algorithm on 400,000 randomly selected image patches. Here are the resulting filters:
 I then used the filters to compress the following image:
 Using the maximum compression level, JPEG compresses the image to 7.1KiB:
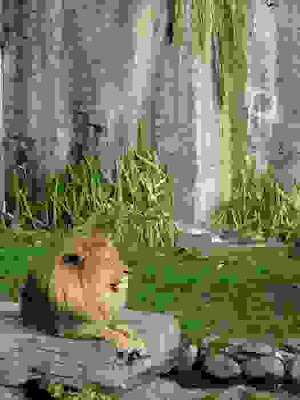 My compression algorithm compresses the image to 5.6KiB:
 Try clicking on the above images to see the high resolution versions. My compressed version of the image is smaller and looks better than JPEG.
I did the compression by doing a raster scan of the image and for each image patch I select the best filter. I then losslessly compress the filter selections using paq8l. The obvious improvement to this algorithm would be to use a combination of several filters for each image patch instead of selecting the best filter. Using several filters would take more space to encode but would result in a much better image approximation. Another idea I plan to try is to use this same algorithm for lossy video compression.
 I then used the filters to compress the following image:
 Using the maximum compression level, JPEG compresses the image to 7.1KiB:
 My compression algorithm compresses the image to 5.6KiB:
 Try clicking on the above images to see the high resolution versions. My compressed version of the image is smaller and looks better than JPEG.
I did the compression by doing a raster scan of the image and for each image patch I select the best filter. I then losslessly compress the filter selections using paq8l. The obvious improvement to this algorithm would be to use a combination of several filters for each image patch instead of selecting the best filter. Using several filters would take more space to encode but would result in a much better image approximation. Another idea I plan to try is to use this same algorithm for lossy video compression.
Tuesday, April 26, 2011
The Sleeping Mind
I occasionally wake up from a dream and immediately realize how flawed my logic was. Although I rarely remember any of my dreams, I have definitely woken up and thought to myself "haha, my sleeping mind must be really stupid to have come up with that conclusion." However, I have encountered a few counterexamples which indicate that my sleeping mind can be productive.
When I am falling asleep I usually spend my time thinking about some challenging problem. My theory is that if I fall asleep while thinking about a problem, my sleeping mind might churn away during the night and make progress on the problem. Although this usually isn't the case, there have been a few instances when I wake up and I have the answer.
A few years ago I was stuck on a programming problem on a cpsc313 assignment. It was late at night, I wasn't making any progress, so I went to sleep. I woke up in the middle of the night and immediately knew how to solve the question. I was so excited that I spent a few minutes implementing the solution, verified that it worked, and then went back to sleep.
Last night I went to sleep trying to think of an idea for a project to implement on Google App Engine. This morning I was surprised to find that I had a complete project idea in mind (including the algorithms needed to implement it!). I don't particularly like the idea and I don't think I will implement it, but I was shocked to find that I could come up with an original idea with non-trivial algorithmic details while I was asleep.
The idea was to develop a website for people looking for recommended places to travel. The website would first ask a series of 5-10 binary questions. The questions would provide a brief description of two travel destinations. The user would then click on the destination they would prefer travelling to. After they complete the questions a ranked list of travel recommendations would be given to the user (the list would contain many more destinations than were asked in the questions). Using some basic machine learning, the travel recommendations would become more accurate as more people use the website. The answers to the questions serve two purposes: 1) to assign the user to a cluster of like-minded individuals in order to generate a ranked destination list and 2) to rank travel destinations for all users in that cluster. Although I don't particularly like this project idea, I do like the algorithm it uses. I can imagine that this same algorithm could be used for other project ideas (although I haven't thought of any good ones yet).
When I am falling asleep I usually spend my time thinking about some challenging problem. My theory is that if I fall asleep while thinking about a problem, my sleeping mind might churn away during the night and make progress on the problem. Although this usually isn't the case, there have been a few instances when I wake up and I have the answer.
A few years ago I was stuck on a programming problem on a cpsc313 assignment. It was late at night, I wasn't making any progress, so I went to sleep. I woke up in the middle of the night and immediately knew how to solve the question. I was so excited that I spent a few minutes implementing the solution, verified that it worked, and then went back to sleep.
Last night I went to sleep trying to think of an idea for a project to implement on Google App Engine. This morning I was surprised to find that I had a complete project idea in mind (including the algorithms needed to implement it!). I don't particularly like the idea and I don't think I will implement it, but I was shocked to find that I could come up with an original idea with non-trivial algorithmic details while I was asleep.
The idea was to develop a website for people looking for recommended places to travel. The website would first ask a series of 5-10 binary questions. The questions would provide a brief description of two travel destinations. The user would then click on the destination they would prefer travelling to. After they complete the questions a ranked list of travel recommendations would be given to the user (the list would contain many more destinations than were asked in the questions). Using some basic machine learning, the travel recommendations would become more accurate as more people use the website. The answers to the questions serve two purposes: 1) to assign the user to a cluster of like-minded individuals in order to generate a ranked destination list and 2) to rank travel destinations for all users in that cluster. Although I don't particularly like this project idea, I do like the algorithm it uses. I can imagine that this same algorithm could be used for other project ideas (although I haven't thought of any good ones yet).
Sunday, April 10, 2011

Sunday, March 27, 2011
RoboCup Iran Open
Next week I was planning to travel to Iran with the UBC RoboCup team to compete in the Iran Open. After the competition I was planning on doing some travelling in Thailand. Unfortunately, the trip got cancelled. Since UBC is one of the team sponsors, they have a policy which requires that we get permission to travel to DFAIT level 3 regions. The official response was that the faculty would not give approval for the trip (due to the current threat level and the fact that the trip is not academically essential). Since we had already purchased plane tickets, the cancellation cost the team quite a bit of money. In July our team will be travelling to Turkey to compete in RoboCup 2011.
Monday, March 21, 2011
html5cards.org
Today I purchased a domain name for the HTML5 card game website Simon and I have been working on: html5cards.org
Tuesday, March 15, 2011
HTML5 Card Games
Simon and I have been making steady progress on our multiplayer card game website. The project is currently hosted at http://html5cards.appspot.com. We have implemented one game so far (German Bridge) which should be mostly functional. Let us know if you see any bugs or have feedback.
Tuesday, March 08, 2011
Face Cards
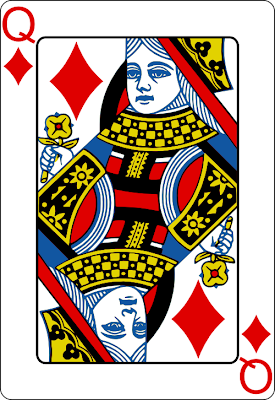
 I have released a new version of my vector playing cards. It turns out the designs for the face cards are in the public domain. I compared several brands of cards and they use the exact same designs. I scanned the cards and vectorized them using potrace. After vectorizing them I did a lot of touch-up work using Inkscape.

Subscribe to:
Posts (Atom)